One successful cooking trial shows that a machine can reach a target under specific conditions. It does not establish whether the same result will occur repeatedly. Starting temperature, cookware position, food quantity, and operator timing can influence the outcome. Buyers need repeated evidence before accepting a claim.
For commercial induction cooking equipment, repeated testing helps evaluate heating time, temperature recovery, and cooking cycle duration. No fixed run count validates every claim. The appropriate count depends on the claimed difference, variation in results, and intended operating conditions.
What Should Each Run Measure?
Repeat testing begins with a precise question. Instead of claiming that water heats quickly, specify its volume, initial temperature, vessel, target temperature, and timing method. For recovery tests, define the added load and the temperature point that marks completion. The start and stop rules must remain unchanged throughout the trial.
Electrical supply, room conditions, cookware dimensions, and power settings should also be recorded. Use the same measuring instrument and placement for comparable trials. If one condition changes, the report should explain why. Otherwise, differences may reflect the setup.
We also recommend defining an acceptable performance difference before testing. Several seconds may be irrelevant in a long cooking cycle, while a similar change could matter during rapid service. The claim should address a practical kitchen requirement rather than an isolated number.
Three Runs Are Only a Starting Point
Three consecutive runs can identify obvious variation or a basic setup problem. However, similar readings from three trials provide limited evidence about consistency. Five to ten controlled runs offer a more useful preliminary comparison, although this range is a practical screening suggestion rather than a universal validation standard.
When the claimed improvement is small or the readings vary widely, more trials may be necessary. Decide the intended run count before collecting results. Stopping immediately after several favorable outcomes creates a misleading picture. Record interrupted or unsuccessful trials, together with the reason for each interruption.
Formal performance claims may require a sample-size calculation based on expected variation and acceptable uncertainty. Testing the same machine repeatedly also differs from testing several production units. Both questions matter, but their results should not be treated as interchangeable.
Why Can Results Change Between Trials?
Cookware is one source of variation. Base diameter, flatness, magnetic properties, and position affect induction coupling. Vessel mass changes how much energy is needed during initial heating. Use the same cookware specification and placement for repeat trials, then report them clearly.
Food preparation introduces further differences. Moisture content, portion size, initial temperature, and stirring can change the heating pattern. During induction appliance engineering evaluations, we distinguish changes caused by the cooking load from those associated with appliance control. This distinction helps prevent unsupported claims about temperature accuracy.
Residual heat can influence later runs, especially when tests follow one another quickly. Establish a consistent starting condition and document cooling intervals. Where several machines are compared, varying their testing order can reduce bias from room conditions or operator fatigue.
What Does the Data Actually Show?
The average does not describe every outcome. Reports should include individual readings, the mean or median, and a measure of variation. The range is easy to interpret, while standard deviation provides another useful measure when enough readings are available. Unusual results should be investigated, not quietly discarded.
Consider two appliances that each average six minutes in a water-heating test. One repeatedly finishes near that time, while the other produces a wide spread of results. The second result may complicate scheduling in a busy kitchen, even though both averages match. Repeatability therefore deserves attention alongside speed.
Plotting results in their original sequence may reveal gradual warming, control changes, or measurement drift. Repeating the same procedure on another day can also help identify differences that a single session misses. Separate these findings from claims about long-term durability.
How Should Product Features Enter the Test?
Buyers should request a documented method, raw results, measurement equipment details, and records of deviations. The report should identify which features were examined and which were not. Heating-time results do not establish electronic protection reliability.
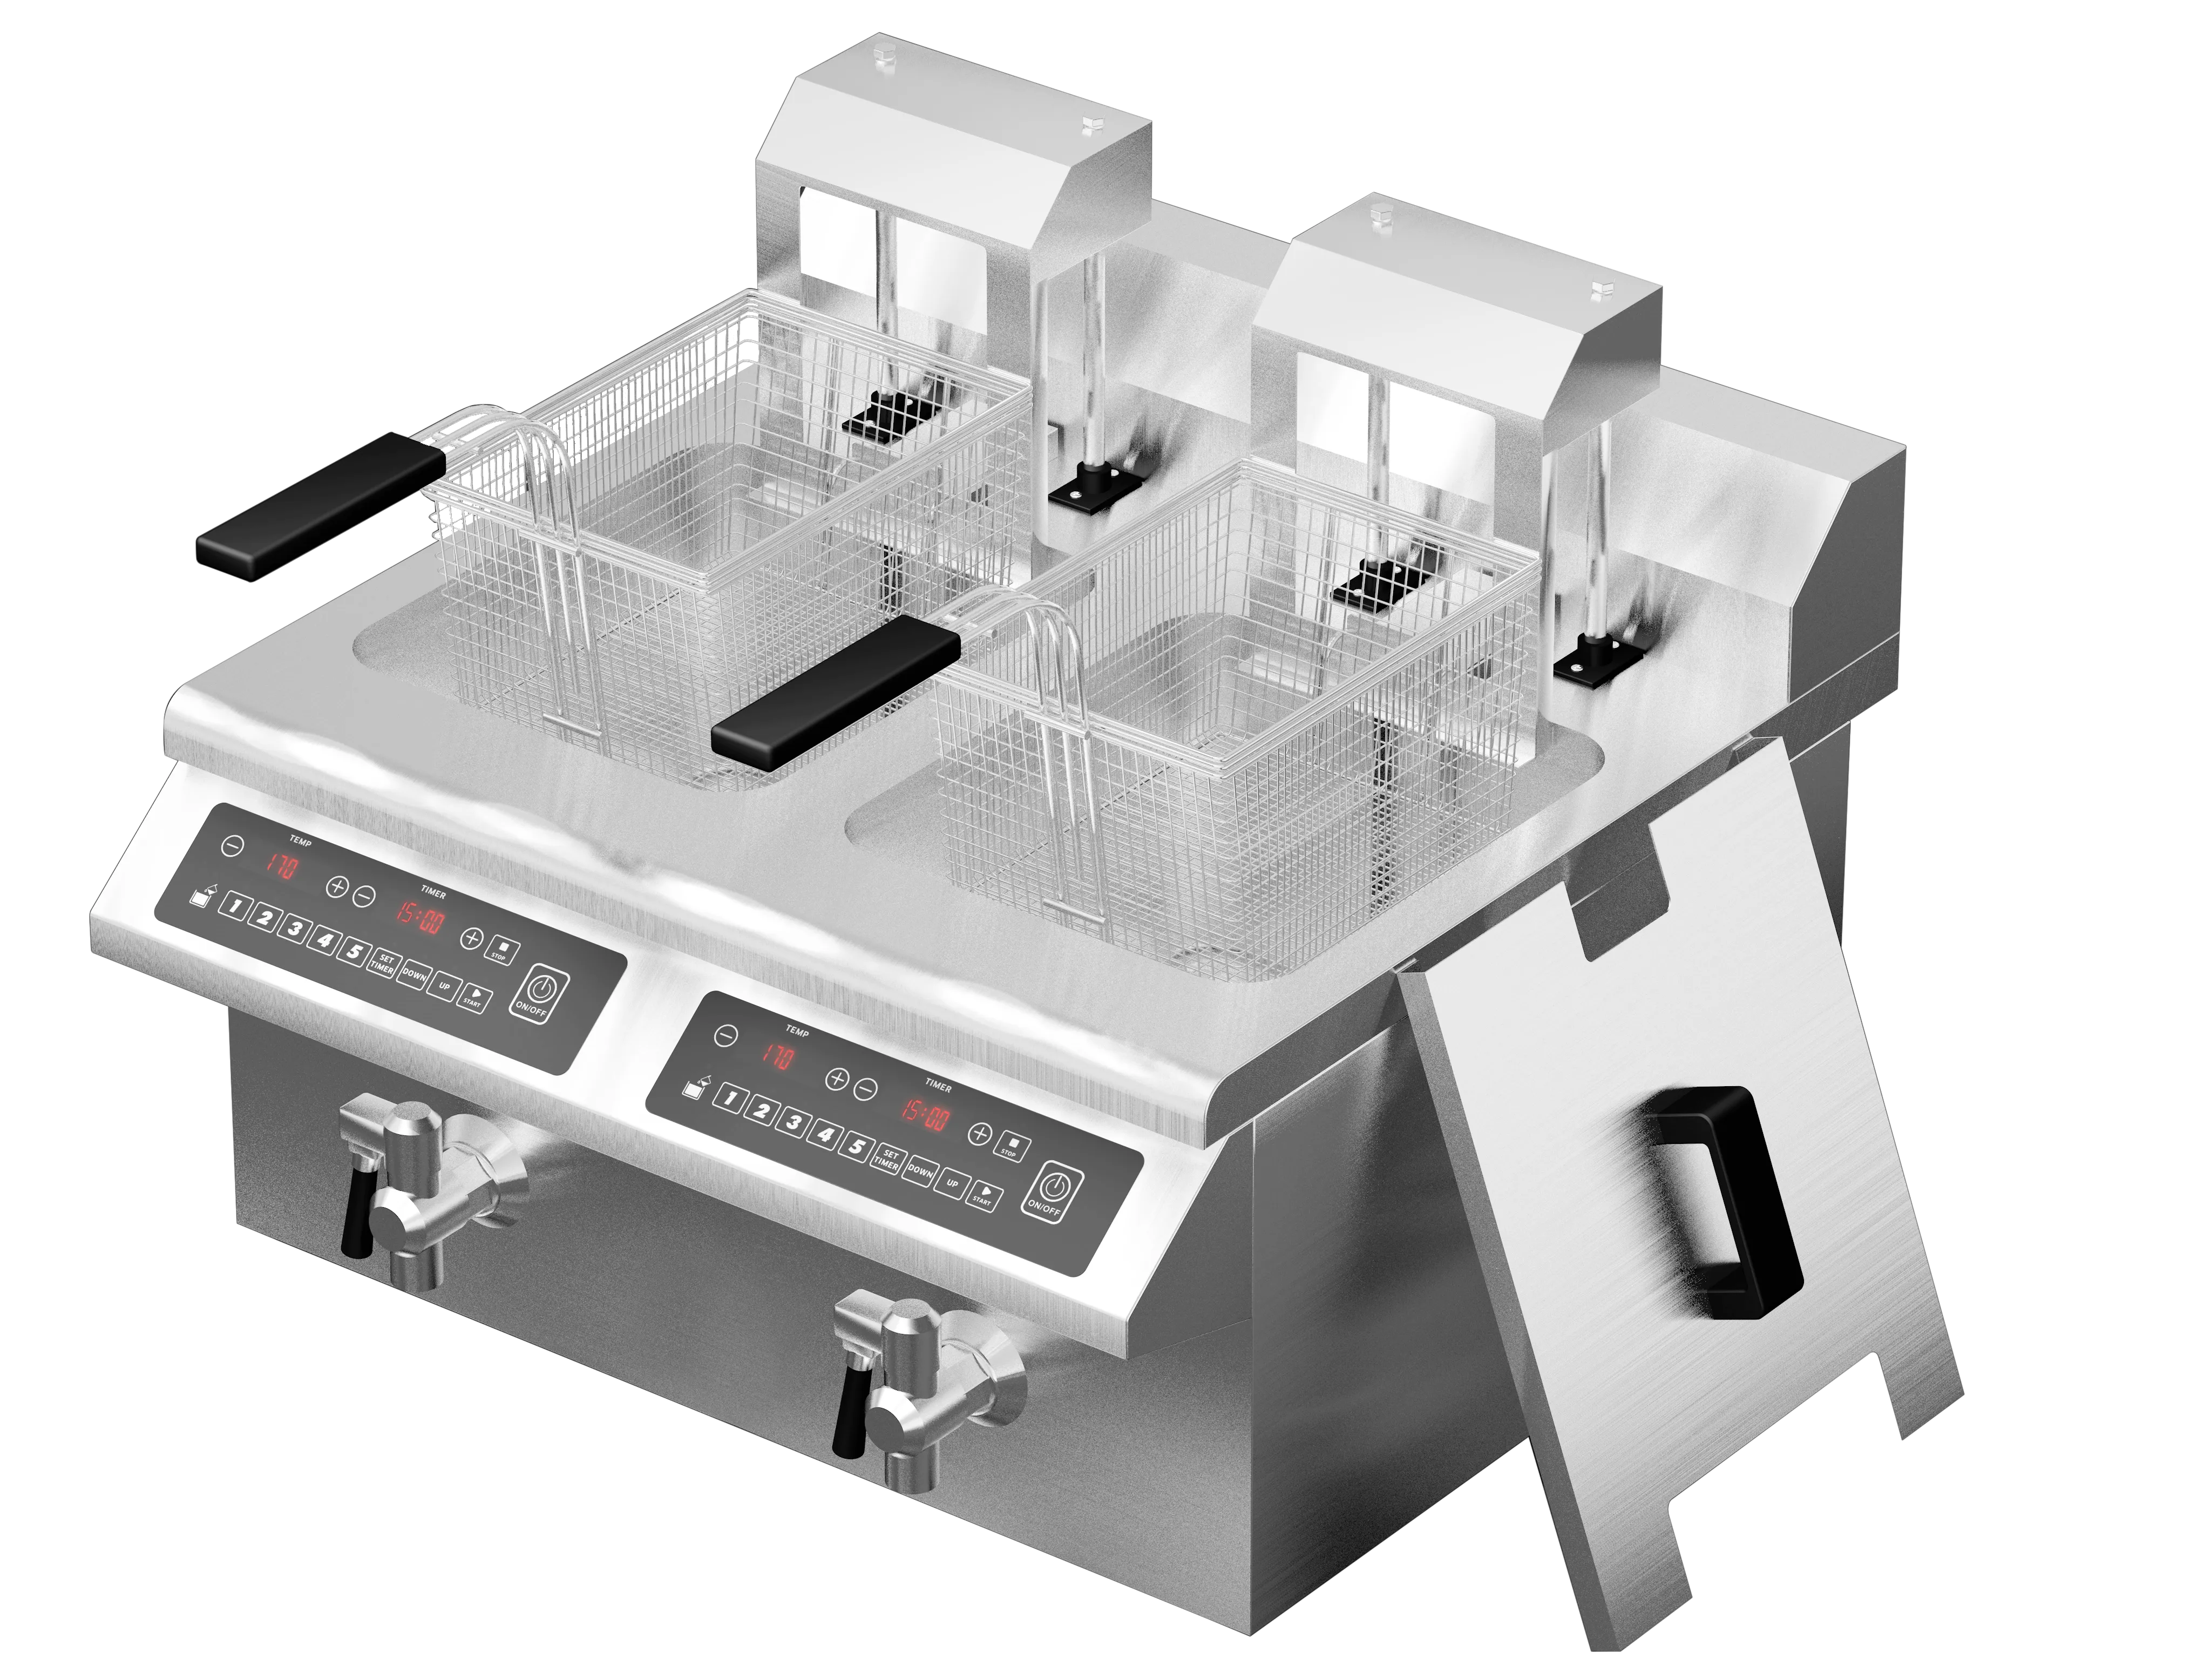
Within our ODM and OEM work at Better Induction, we develop and manufacture induction cooking products for customers' branded ranges. The E350Z8F2-L has a stainless steel body, auto-lift function, touch control, two-plug cord, and electronic overheating protection. Those specifications describe its configuration; they do not demonstrate repeatable heating performance.
When planning a model-specific trial, we relate each measurement to its purpose. Auto-lift operation, control response, and heating consistency require distinct procedures. This keeps the discussion focused on measured evidence.
When Is the Evidence Credible Enough?
Repeat runs make a claim more credible when testing conditions are defined and the spread of results is disclosed. For commercial induction cooking equipment, three trials can flag obvious issues, while five to ten provide preliminary evidence. Stronger comparisons may need additional runs and multiple units, depending on the claim.
At Better Induction, we encourage customers to define their intended cookware, cooking load, power supply, and acceptance criteria before evaluating results. Clear records also make induction appliance engineering discussions more useful. The strongest conclusion is one that states what was tested, how often it was repeated, and what uncertainty remains.
GET IN TOUCH
Contact With us